v1.7.0Latest release notes

Practise production
without the production.

SnowOps Labs builds a production-shaped Kubernetes cluster on your laptop, breaks it the way real clusters break, and checks whether your fix actually worked. Real Prometheus, real Istio, real failures. Free and open source.

For engineers who passed the CKA and still freeze when the pager goes off.

Watch the setup video
Runs on
macOS · Linux · WSL2
Needs
Docker, 2 CPU / 4 GB
Cloud account
Not required
labctl: break it, fix it
Scenarios
13
Injectable faults
6
Timed challenges
3
Platform components
21
Cluster runtimes
3
How it works

Build, simulate, break, measure

Build a realistic platform, run a scenario on it, break it on purpose, and find out how you did. One CLI, labctl, drives all four.

Loop 1 of 4

Stand up a production-shaped cluster

One command creates a local k3d cluster and installs a real platform on it: Traefik for ingress, Prometheus and Grafana for metrics. Add logs, traces, GitOps, a service mesh, secrets or autoscaling when a scenario needs them.

  • Installs kubectl, helm and k3d for you, no sudo
  • Swap Traefik for Nginx, or Istio for Linkerd
  • Checks Docker has room before it starts
run it
labctl init
Try it here

The incident room

These are the real faults from the lab, with the same descriptions and the same hints labctl gives you. Start the clock and see how far you get before you need one.

Fault library
Standing bybad-deploy-rollout
MTTR00:00
Hints0/3
Score100
Medium severityWorkload

Bad deploy: image that doesn't exist

What you are told

A release went out referencing an image tag that was never pushed. The rollout is stuck - new pods sit in ImagePullBackOff while the old version keeps serving.

This is a dry run in the browser, not a live cluster. In the lab the fault breaks a running app and a check against the cluster decides whether you fixed it.

What's in the lab

Scenarios, faults and challenges

Scenarios with checks that grade you, reversible faults with hints, and timed challenges with par times. All of it is YAML and shell in the repo, so you can read exactly what each one does.

13 scenarios

Scenarios

  • ScalabilityVerified

    Autoscaling Under Load

    Watch KEDA scale go-api on Prometheus RPS: a spike drives it from 1 to several replicas, then cooldown brings it back. The flagship 'autoscaling actually works' demo, verified under traffic from the load generator.

    labctl scenario up autoscaling-under-load1 stageSource
  • ReliabilityVerified

    Chaos Engineering

    Run the chaos engineering loop against go-api with Chaos Mesh: establish a steady state under load, form a hypothesis, inject a failure (pod kill, network delay, CPU and memory stress) and measure the blast radius on a Grafana dashboard. go-api ships as a single replica behind a PodDisruptionBudget, so it starts out with disruptionsAllowed=0: a node drain would block forever while a pod kill is still a full outage. Your job is to find that with an experiment and fix it, then prove the same experiment no longer hurts.

    labctl scenario up chaos-engineeringSource
  • CostVerified

    Cost & Capacity: Right-Sizing Over-Provisioned Resources

    go-api arrives reserving 2000m CPU and 1Gi of memory - forty times what it uses. Drive real traffic, read the gap between reserved and used on the dashboard and in OpenCost, then right-size the requests. Grading has two sides: a request over the waste ceiling fails, and so does one under the peak the workload actually reached, because under-provisioning is how workloads get throttled and OOM-killed.

    labctl scenario up cost-right-sizing1 stageSource
  • OperationsVerified

    Day-2 Drill: Namespace Backup & Restore

    Rehearse the loop every operator needs before they need it. Capture a namespace to a manifest archive with 'kubectl get -o json | jq', delete something that matters, and put it back with 'kubectl apply --server-side'. Then find the edge of what that buys you: a data-writer holds a boot-id on a PersistentVolume, and restoring its claim gives you back the object bound to a brand-new empty disk. The objects round-trip; the bytes do not. A dependency-light way to learn where a manifest backup stops and a volume snapshot has to start.

    labctl scenario up backup-restore-drill2 stagesSource
  • OperationsVerified

    Day-2 Drill: Node Drain Under Load

    Take a worker node out of service while go-api serves live traffic. labctl gives the workload enough replicas to survive; you write the PodDisruptionBudget, cordon and drain the node with kubectl, watch the pods reschedule, and put the node back. The grade is the measured request success rate across the window.

    labctl scenario up node-drain-drill1 stageSource
  • OperationsVerified

    Day-2 Drill: Rolling Cluster Upgrade Under Load

    Roll the cluster's worker nodes onto a new Kubernetes version one at a time while go-api serves live traffic. You write the PodDisruptionBudget, you cordon and drain each node, and you watch the PDB block the eviction that would have taken the app down. The grade is the measured request success rate across the upgrade window and a cluster left with no node behind.

    labctl scenario up cluster-upgrade-drill1 stageSource
  • DataVerified

    Event-Driven Architecture

    An 'orders' topic on Kafka (Strimzi) with a producer/consumer flow already running, and producers ramped to five times what the consumer group can process. Orders are piling up. Diagnose the backlog from Kafka's own tooling and from the lag dashboard, then restore throughput by scaling the group up to the topic's partition count, and no further, because a fourth consumer gets no partition and adds nothing.

    labctl scenario up event-driven-arch2 stagesSource
  • DeliveryVerified

    GitOps & CI/CD (ArgoCD)

    Run a real GitOps loop against a Git repository you can actually push to. The lab serves its own repo in-cluster; ArgoCD reconciles it. You clone it, change the declared image and replica count, push, and watch the cluster follow, then prove the three things that make GitOps different from kubectl: self-heal reverts a change you make by hand, prune deletes a resource you remove from Git, and a release that syncs perfectly can still be broken - the lab ships one that is, and you repair it in Git.

    labctl scenario up gitops-cicd4 stagesSource
  • NetworkingVerified

    Mesh Traffic Management

    Run a canary release for go-api on Istio. labctl stages two versions behind one Service and a meshed load client; you write the routing. Shift a 90/10 weighted split, rehearse a slow release with a header-matched latency fault, and lock the canary down with STRICT mTLS, then prove each one from mesh telemetry rather than from the fact that a CR exists.

    labctl scenario up mesh-traffic-management3 stagesSource
  • DeliveryVerified

    Multi-Env Promotion (Dev → Staging → Prod)

    Run a real release pipeline by hand: build versioned go-api images, deploy one to dev, and promote it forward to staging then prod with plain kubectl. Promotion here is a genuine image rollout (new ReplicaSet), not a ConfigMap edit - you build vNEXT, roll it out per environment, and watch each env's /version change as the release moves down the pipeline.

    labctl scenario up env-promotion4 stagesSource
  • ObservabilityVerified

    Observability & SRE

    labctl stands up the three signals (Loki for logs, Tempo behind an Alloy collector for traces, Prometheus rules and SLO dashboards for metrics) and then leaves the wiring to you. Export go-api's spans through the collector, drive real load with k6, follow one request from a log line to its trace, and take an SRE alert from inactive to firing by breaking readiness on purpose.

    labctl scenario up observability-sre3 stagesSource
  • SecurityVerified

    Secrets Management & Rotation

    A workload mounts a Vault-backed secret that External Secrets keeps in sync. You rotate the value in Vault; it must reach the running pod through ESO and the kubelet with no restart and no redeploy. The grade is what the running container reads from disk.

    labctl scenario up secrets-management1 stageSource
  • SecurityVerified

    Security & Compliance (Audit → Enforce)

    Take a cluster from 'policies exist' to 'policies bite'. Kyverno ships four Pod Security and best-practice ClusterPolicies in Audit mode, so nothing is blocked and every violation lands in a policy report. Your job is the part a real team owns: read the report, remediate the workload at the source, promote the policies to Enforce, prove the admission webhook now rejects a non-compliant Pod, and issue a real TLS certificate from the lab CA with cert-manager - on a namespace that is default-deny in both directions.

    labctl scenario up security-compliance4 stagesSource
No toy clusters

Everything you install is the real thing

The same Helm charts teams run in production: Prometheus, Istio, Kafka, Argo CD. Faults hit real systems, so the dashboards you learn to read here are the ones you have at work.

  • autoscaling

    KEDA

  • chaos

    Chaos Mesh

  • cost

    OpenCost

  • dashboard

    Kubernetes Dashboard

  • data

    KafkaPostgreSQL

  • gitops

    Argo CD

  • ingresspick one

    NginxTraefik

  • logging

    Loki

  • meshpick one

    IstioLinkerd

  • monitoring

    GrafanaPrometheus

  • secrets

    External SecretsVault

  • security

    Network policiesKyvernoSealed Secretscert-manager

  • tracing

    Tempo

Where a category says “pick one”, the lab runs one provider at a time, the same choice a platform team has to make. Swap the provider, run the scenario again, and compare with evidence instead of opinion.

Built into the binary

Use the terminal or the browser

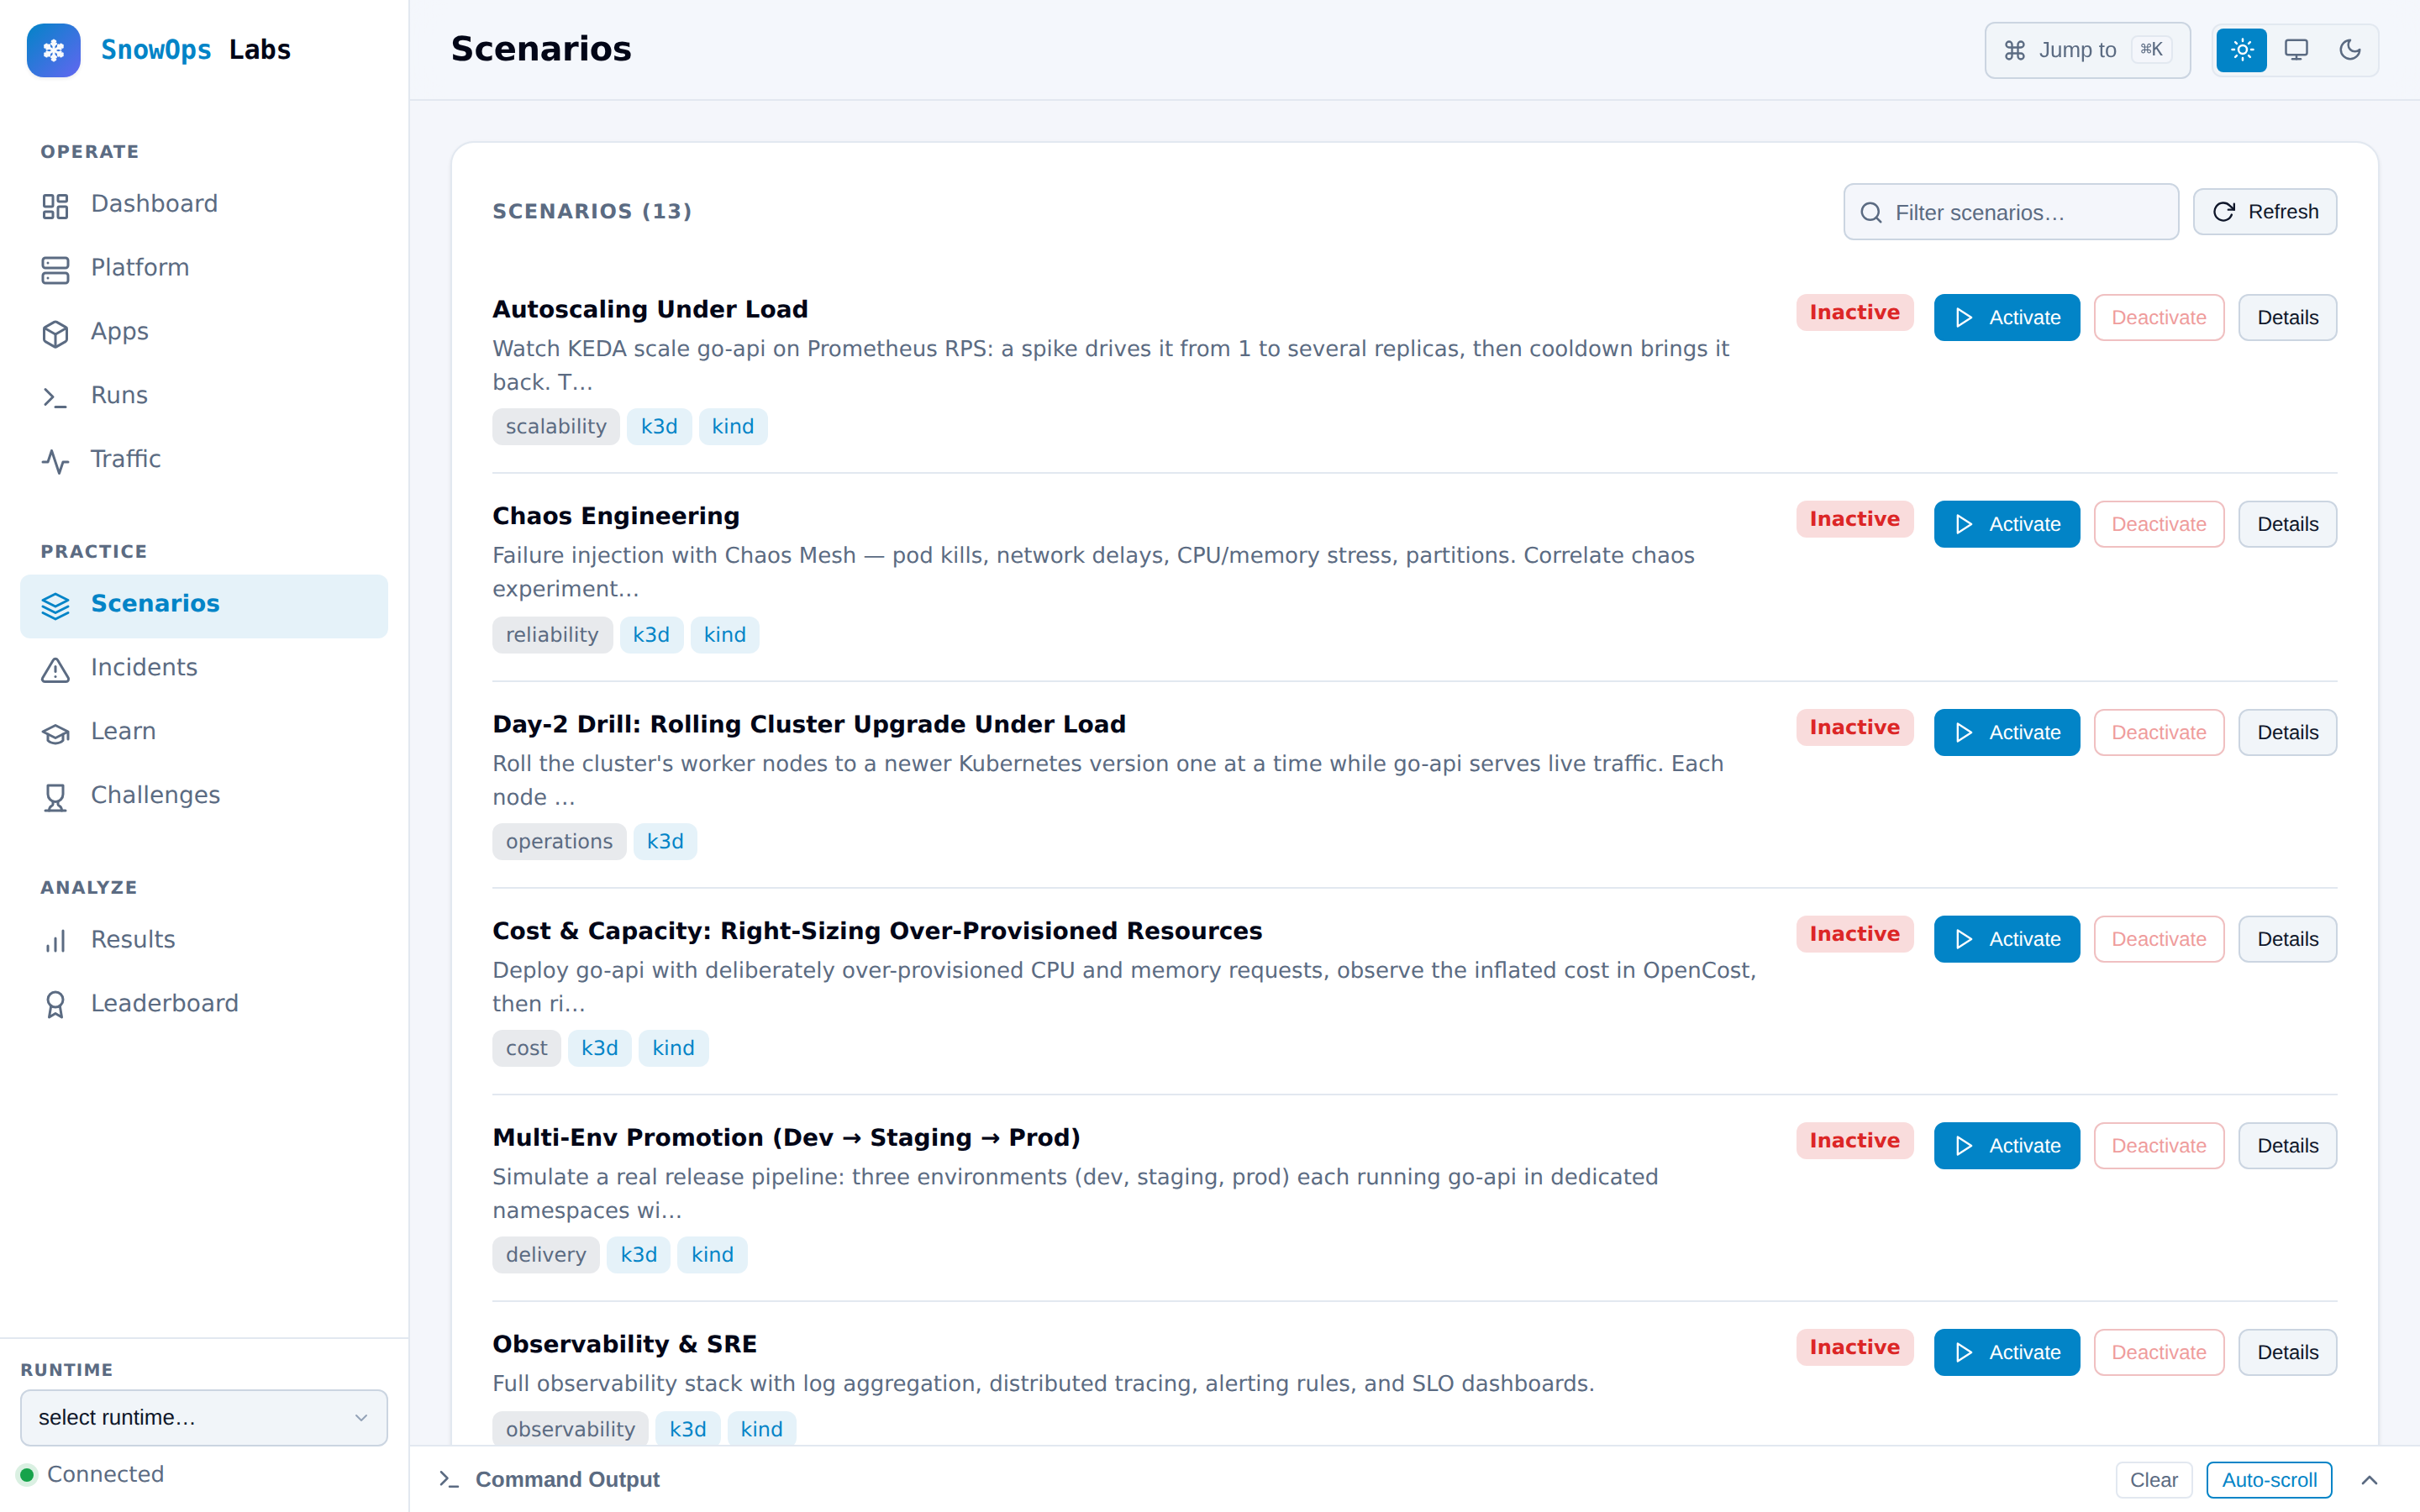
labctl ui serves a web dashboard at localhost:3939. Nothing extra to install, and everything the CLI does is a click away.

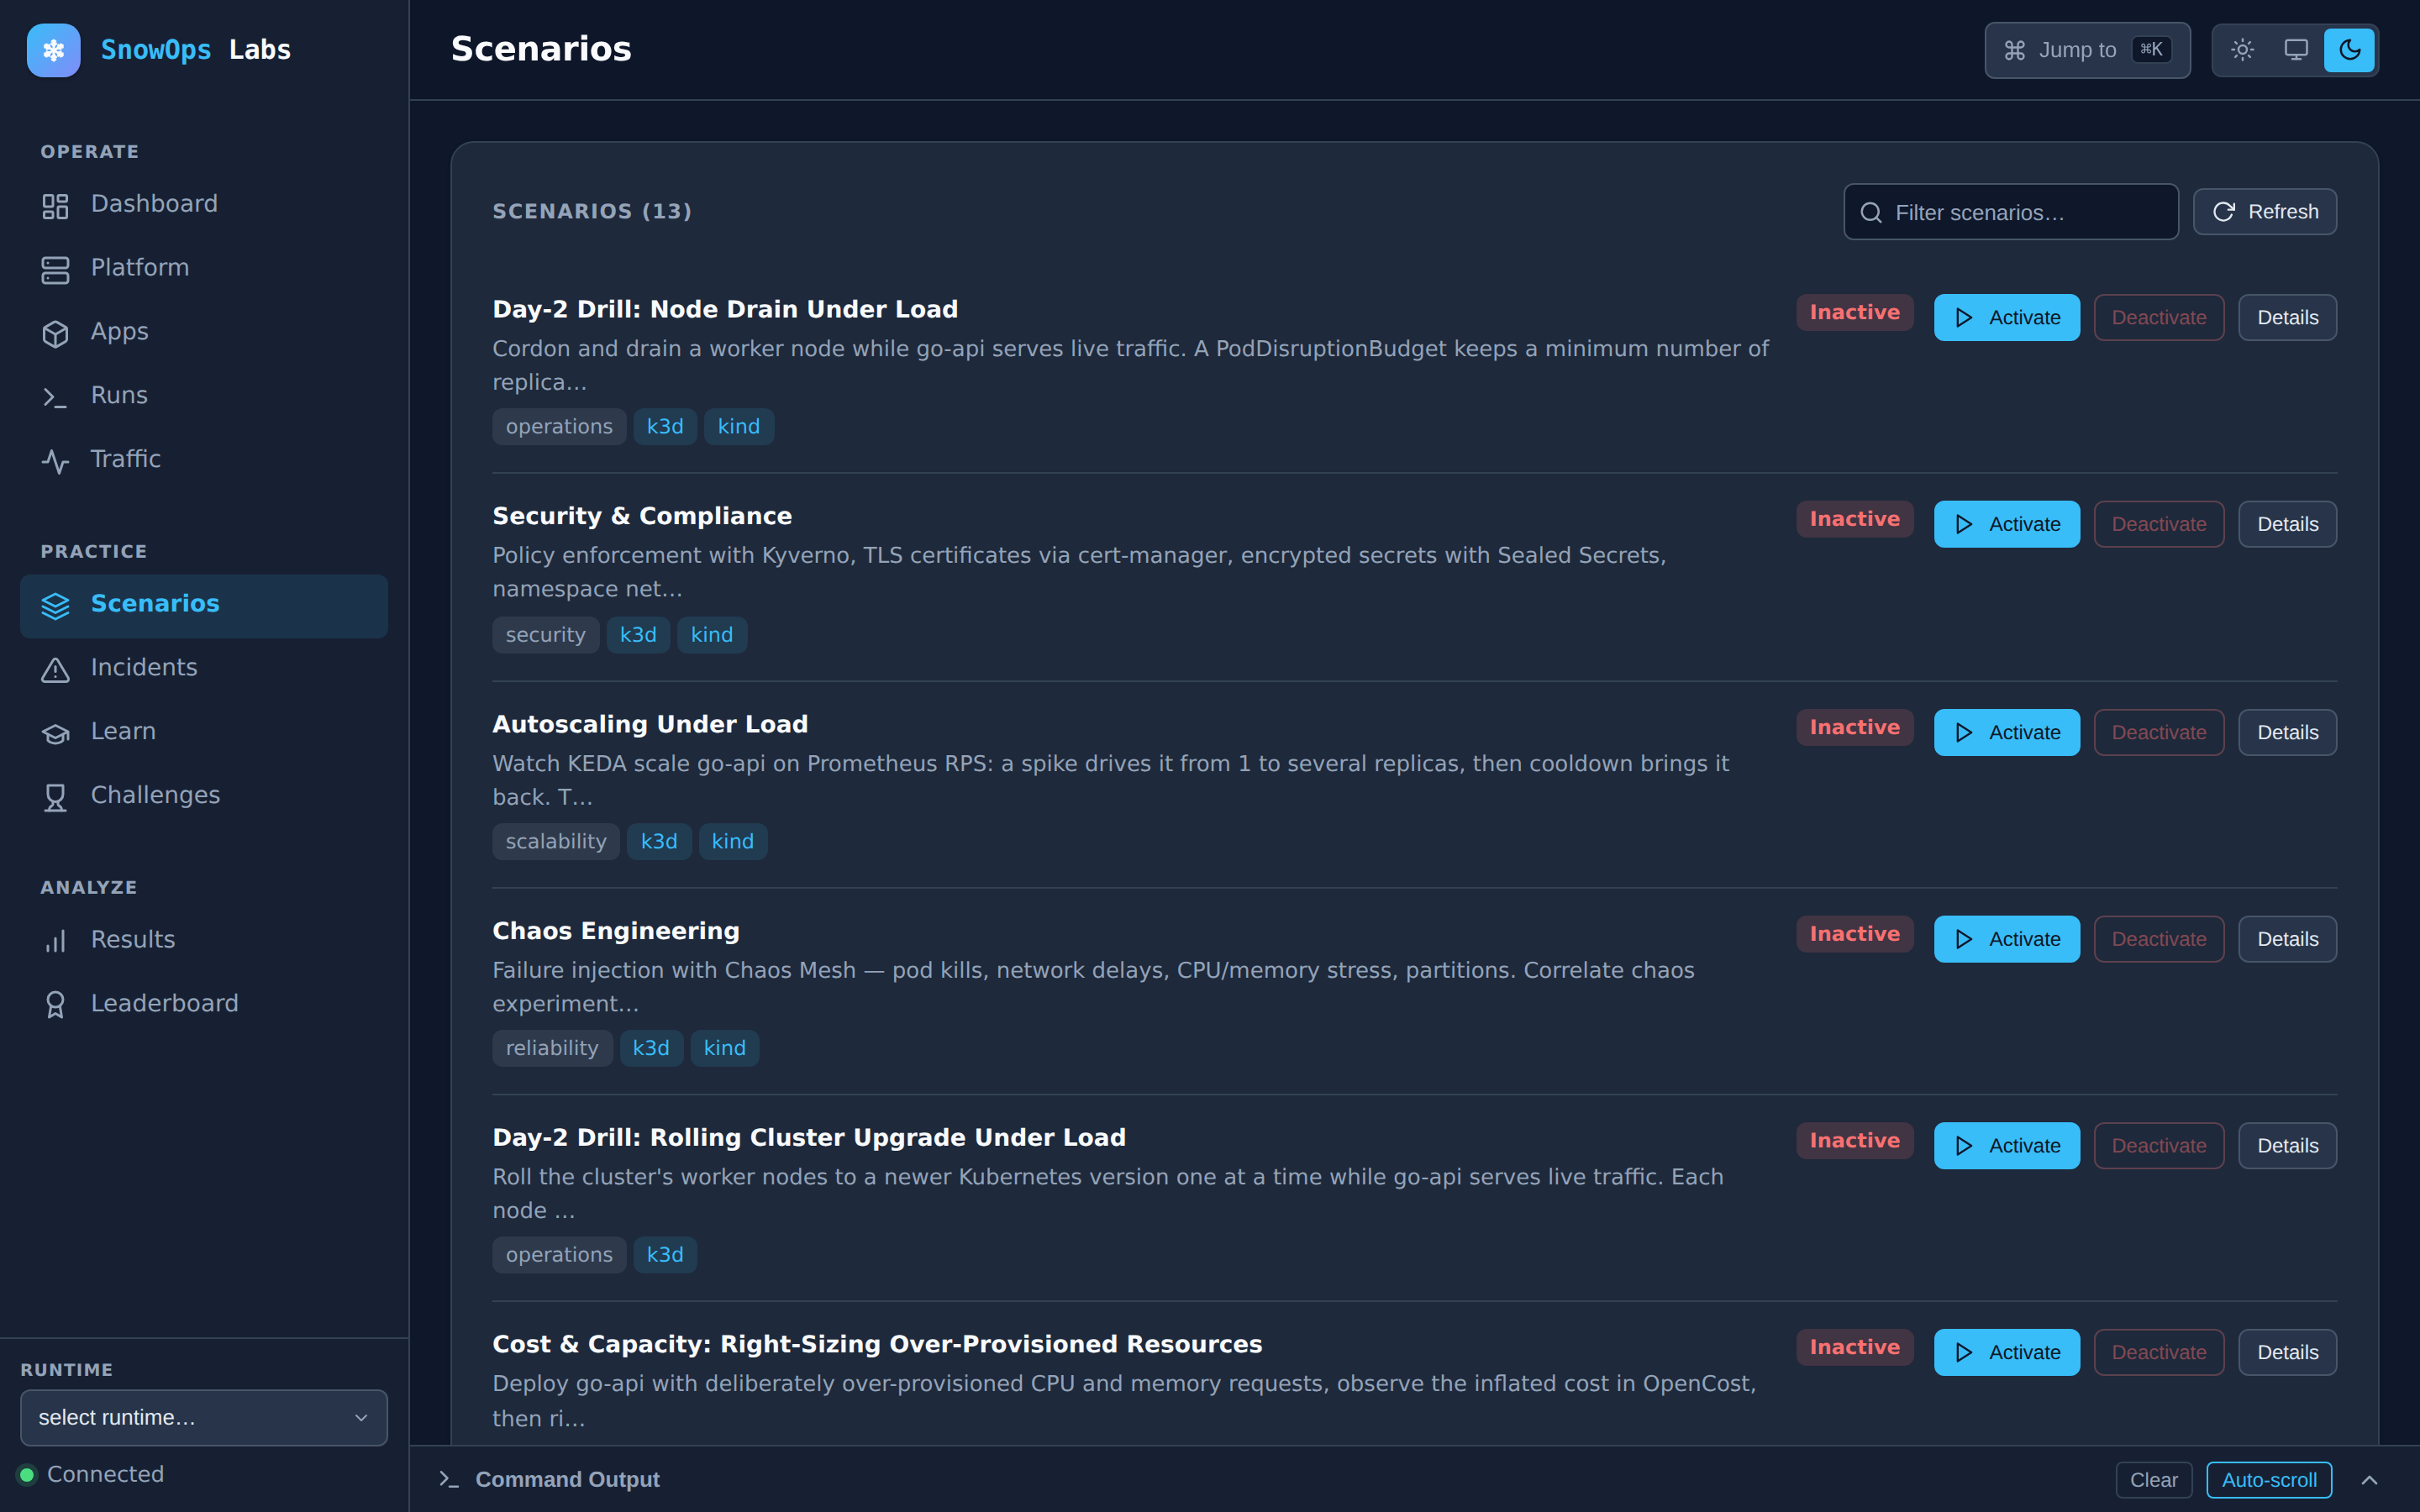
The SnowOps Labs web dashboard showing the scenario catalog, with category tags and one-click activation.The SnowOps Labs web dashboard showing the scenario catalog, with category tags and one-click activation.
The scenario catalog in the dashboard. A real screenshot, not a mockup.
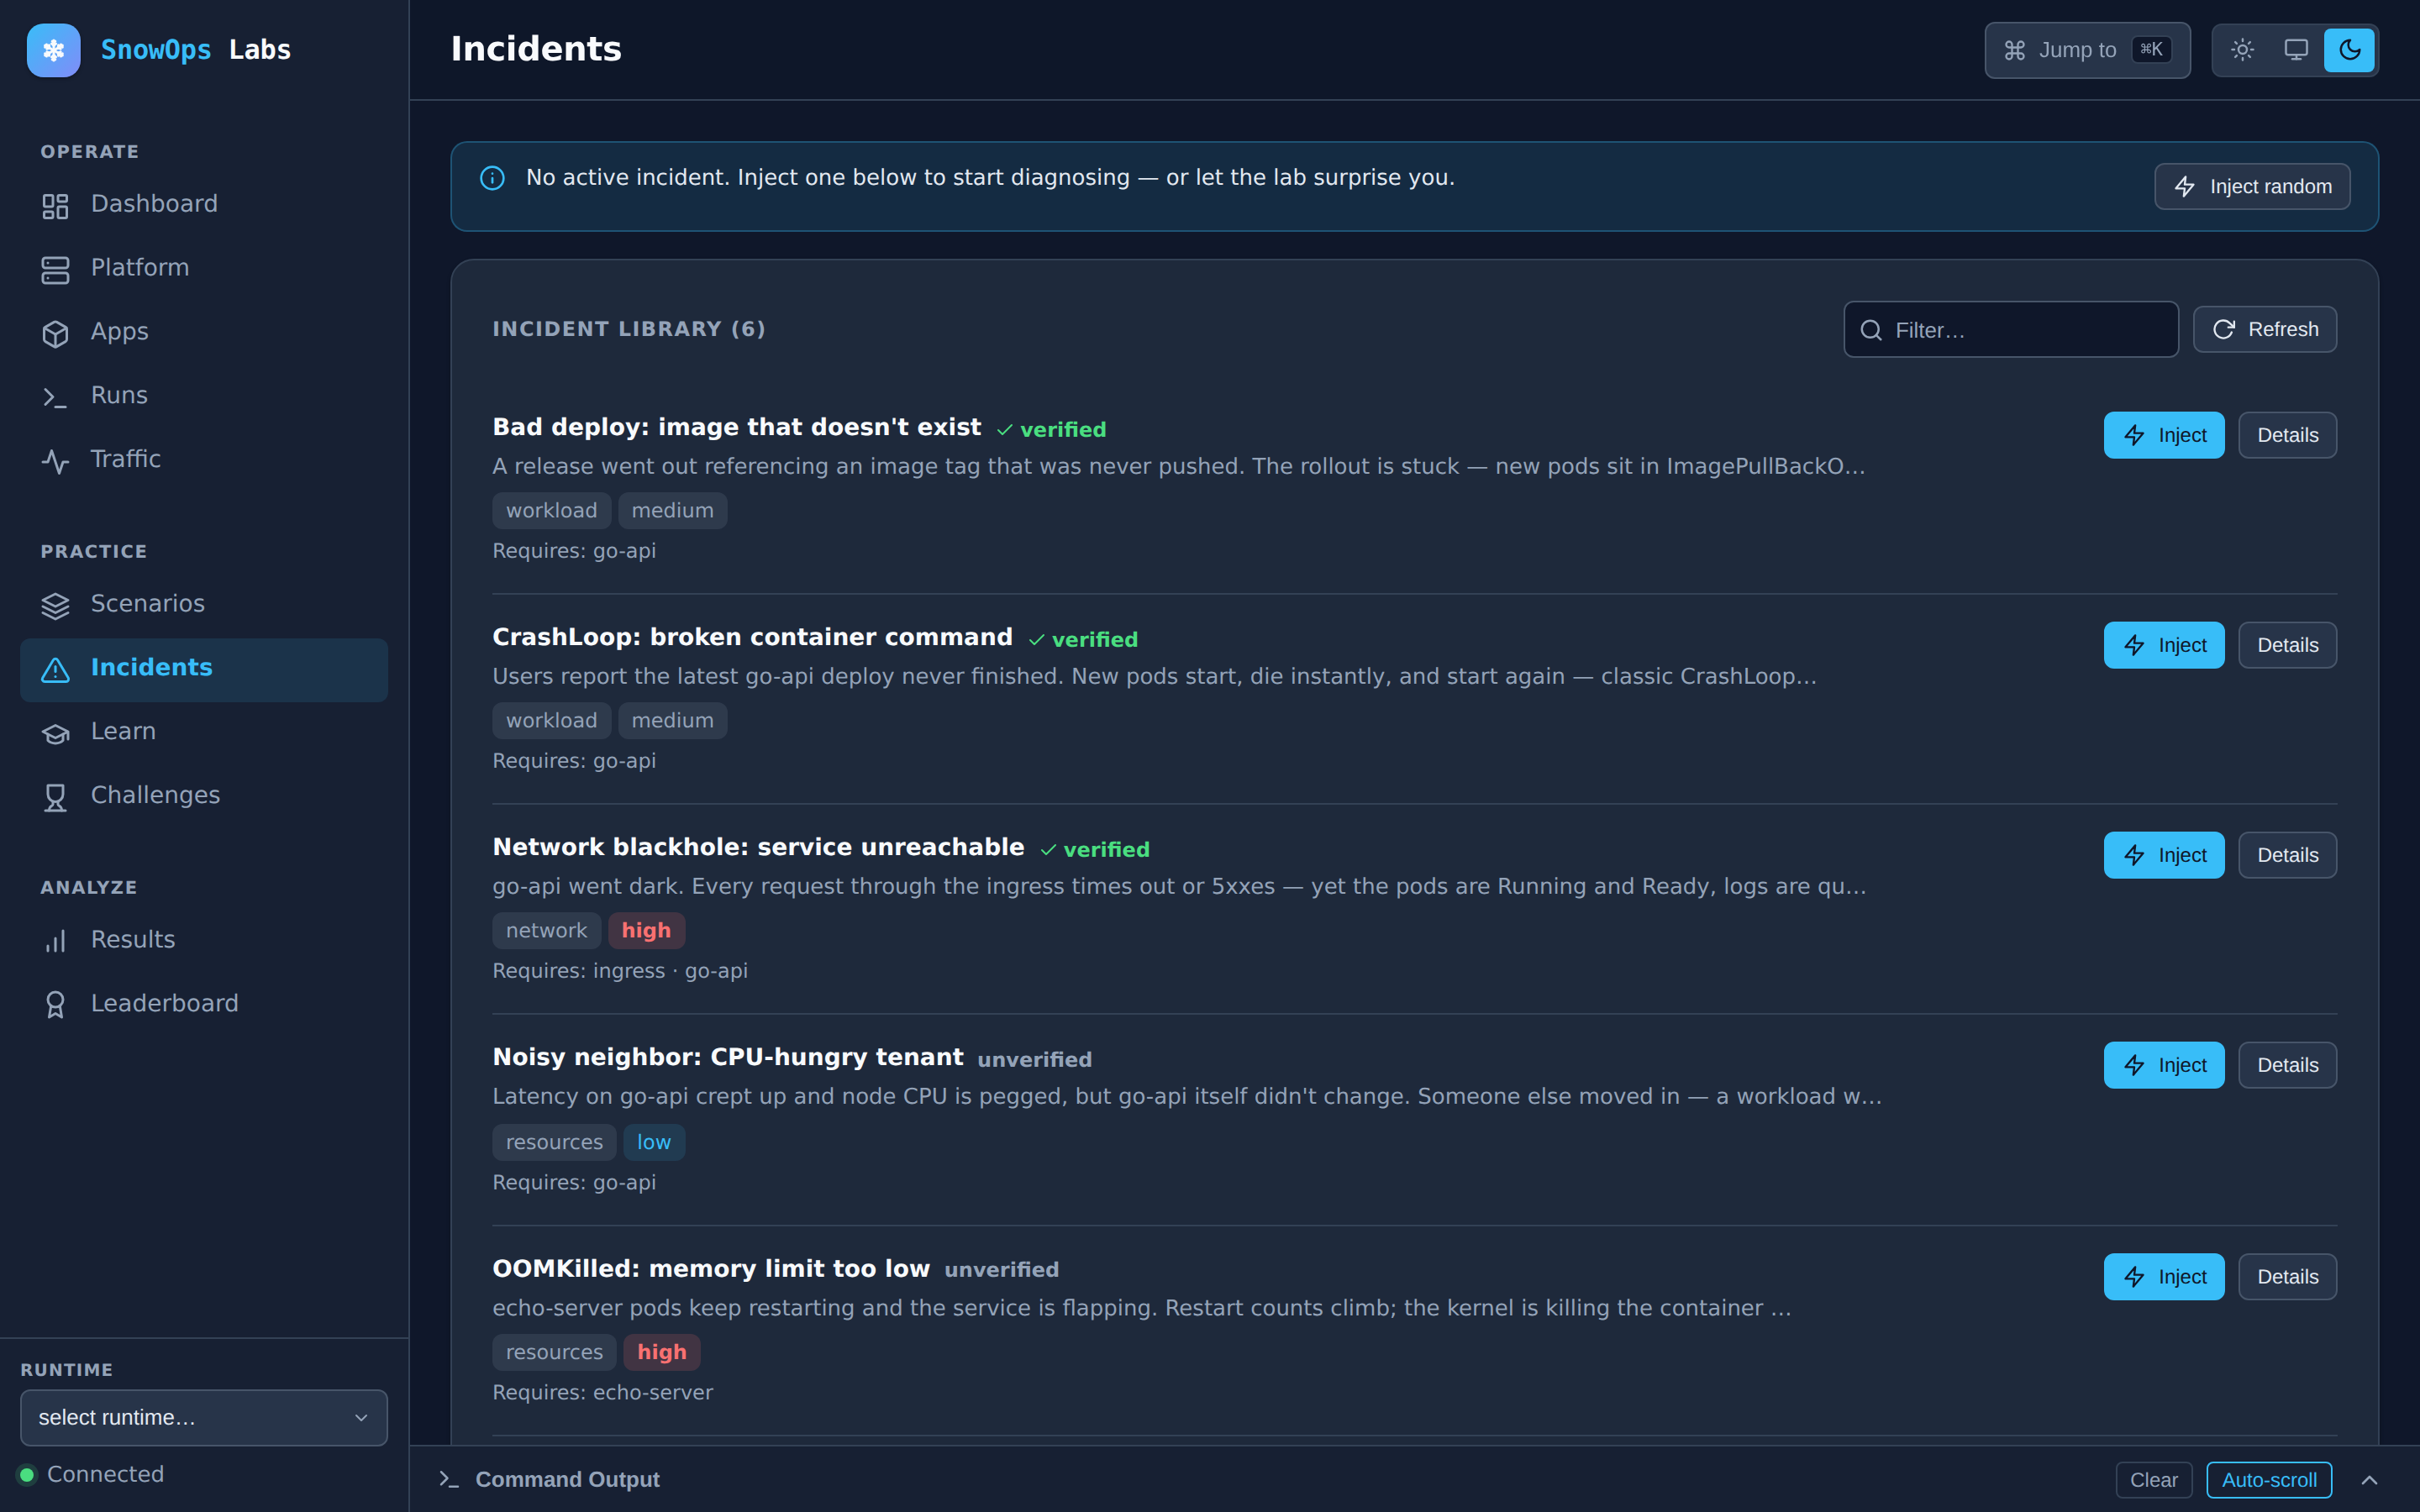
  • The labctl incident library: reversible faults listed with severity and verified badges.
    Fault library
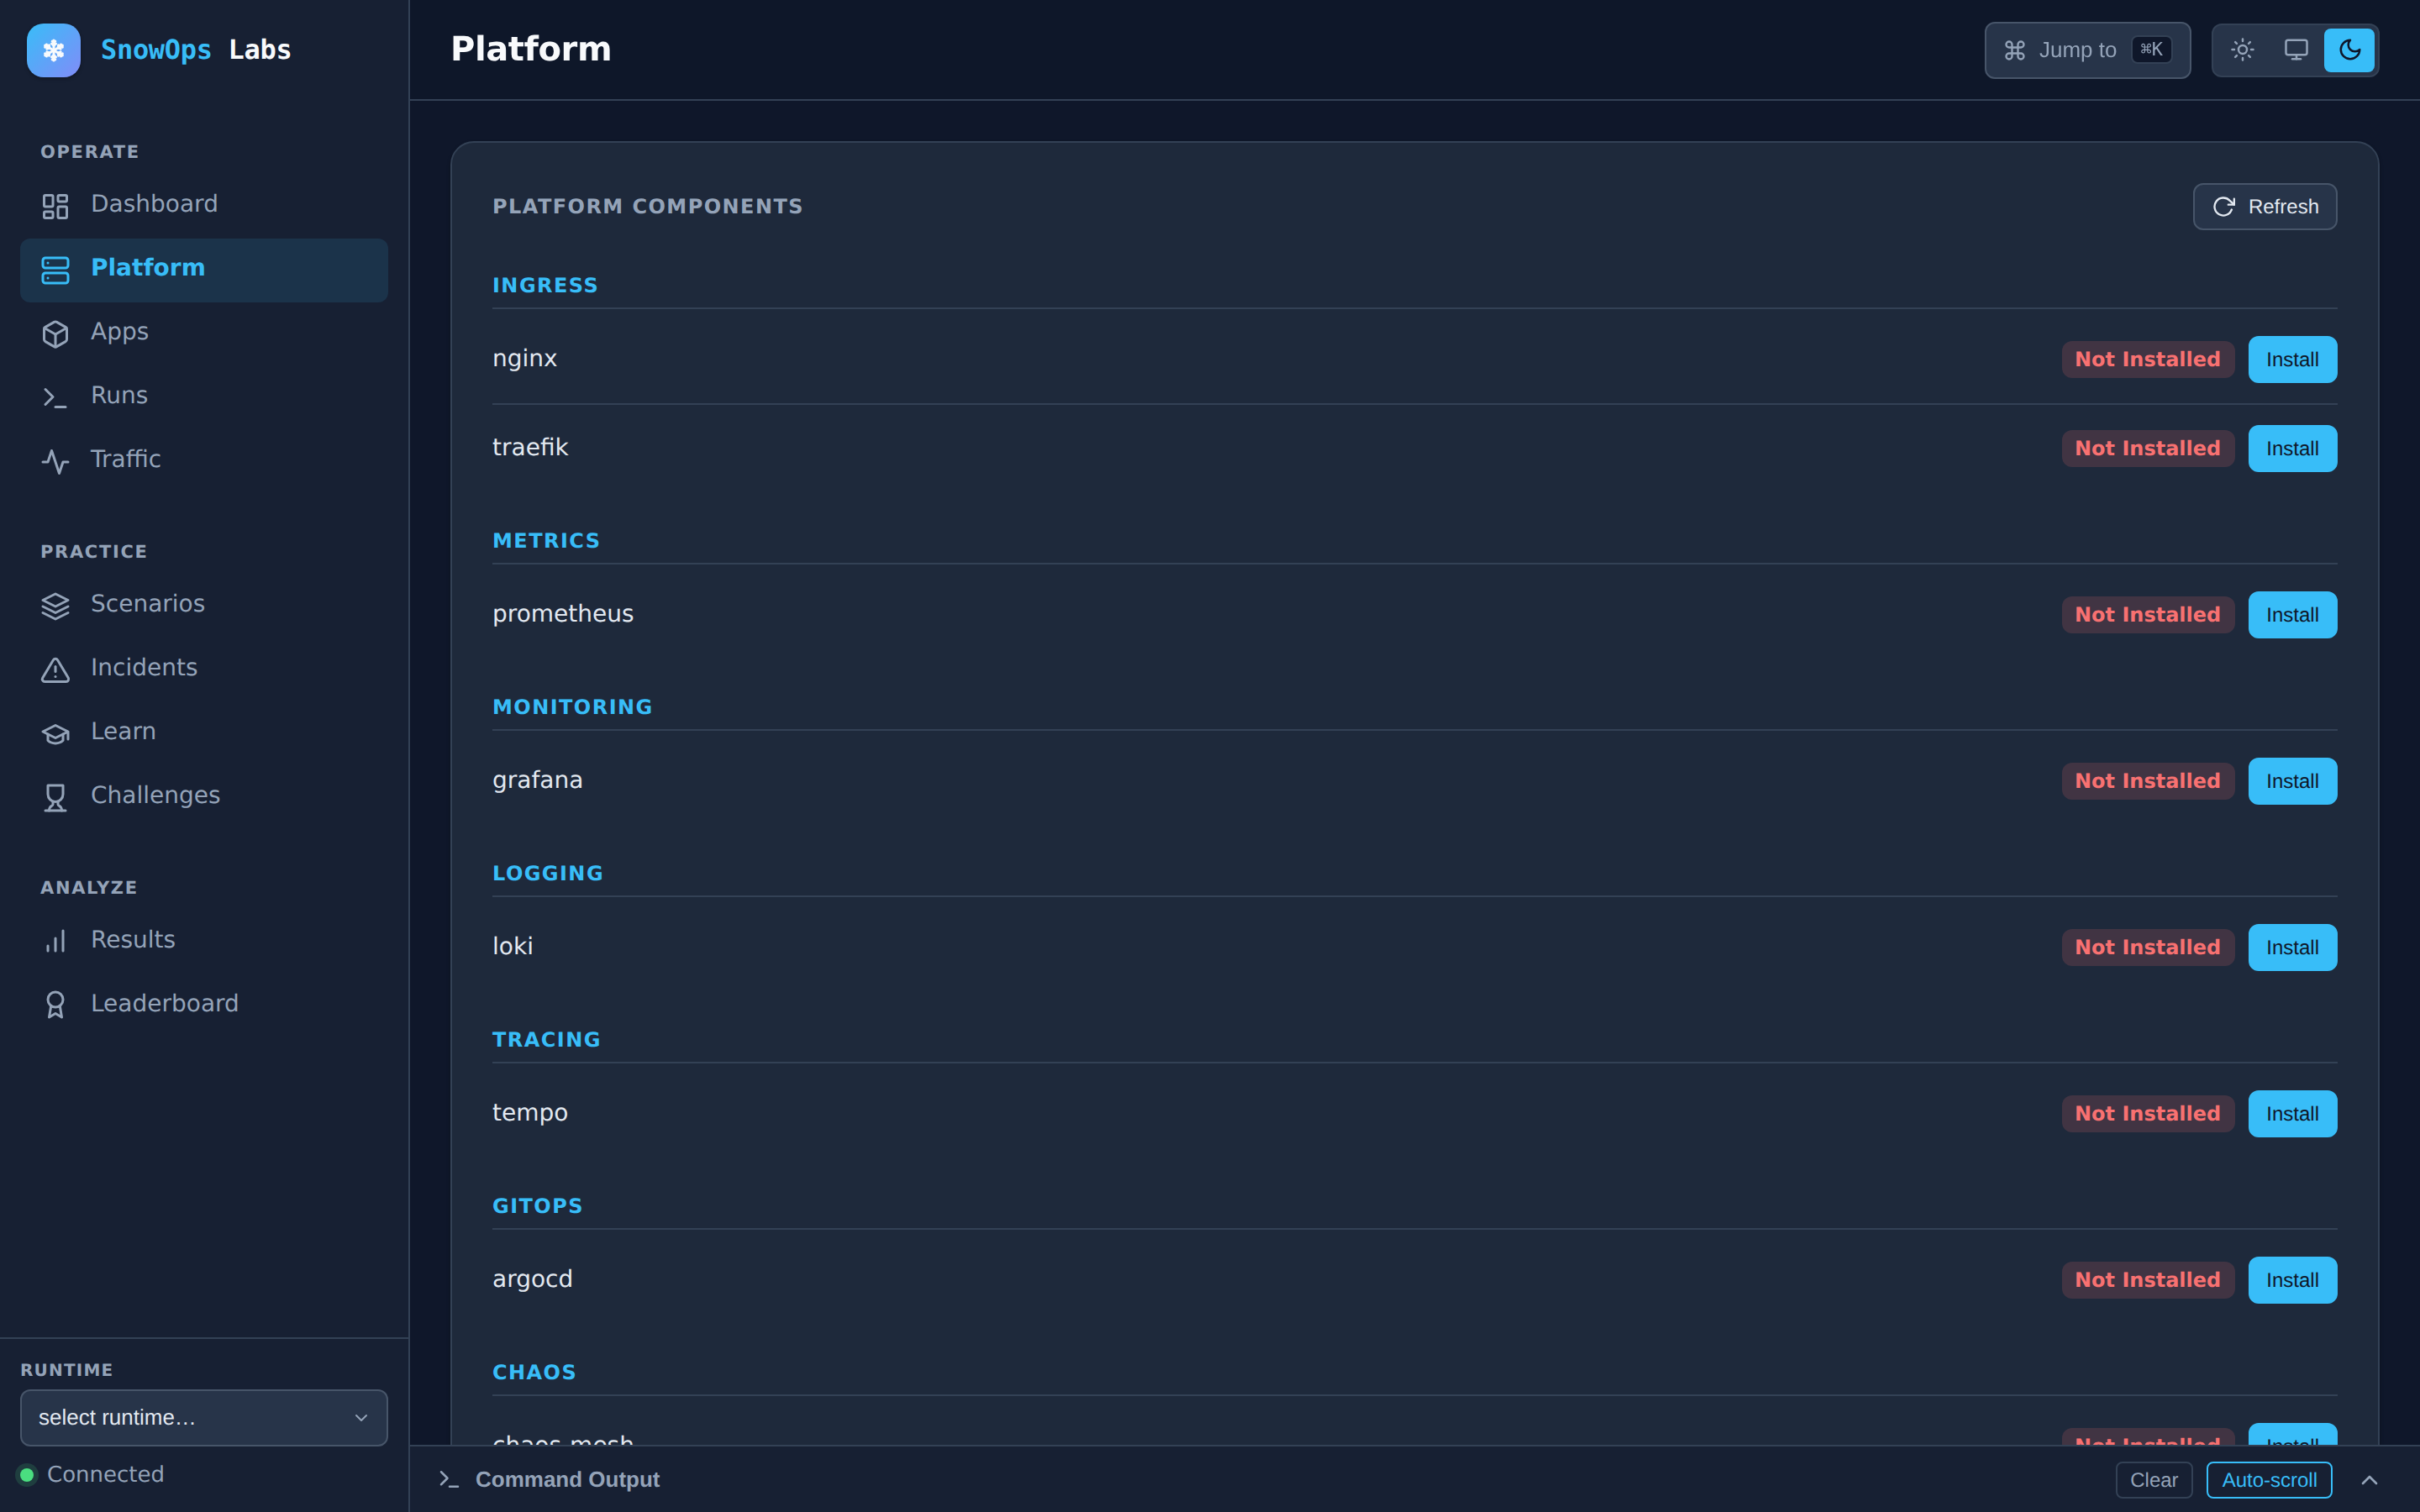
  • Platform components grouped by category, each installable with one click.
    Platform components
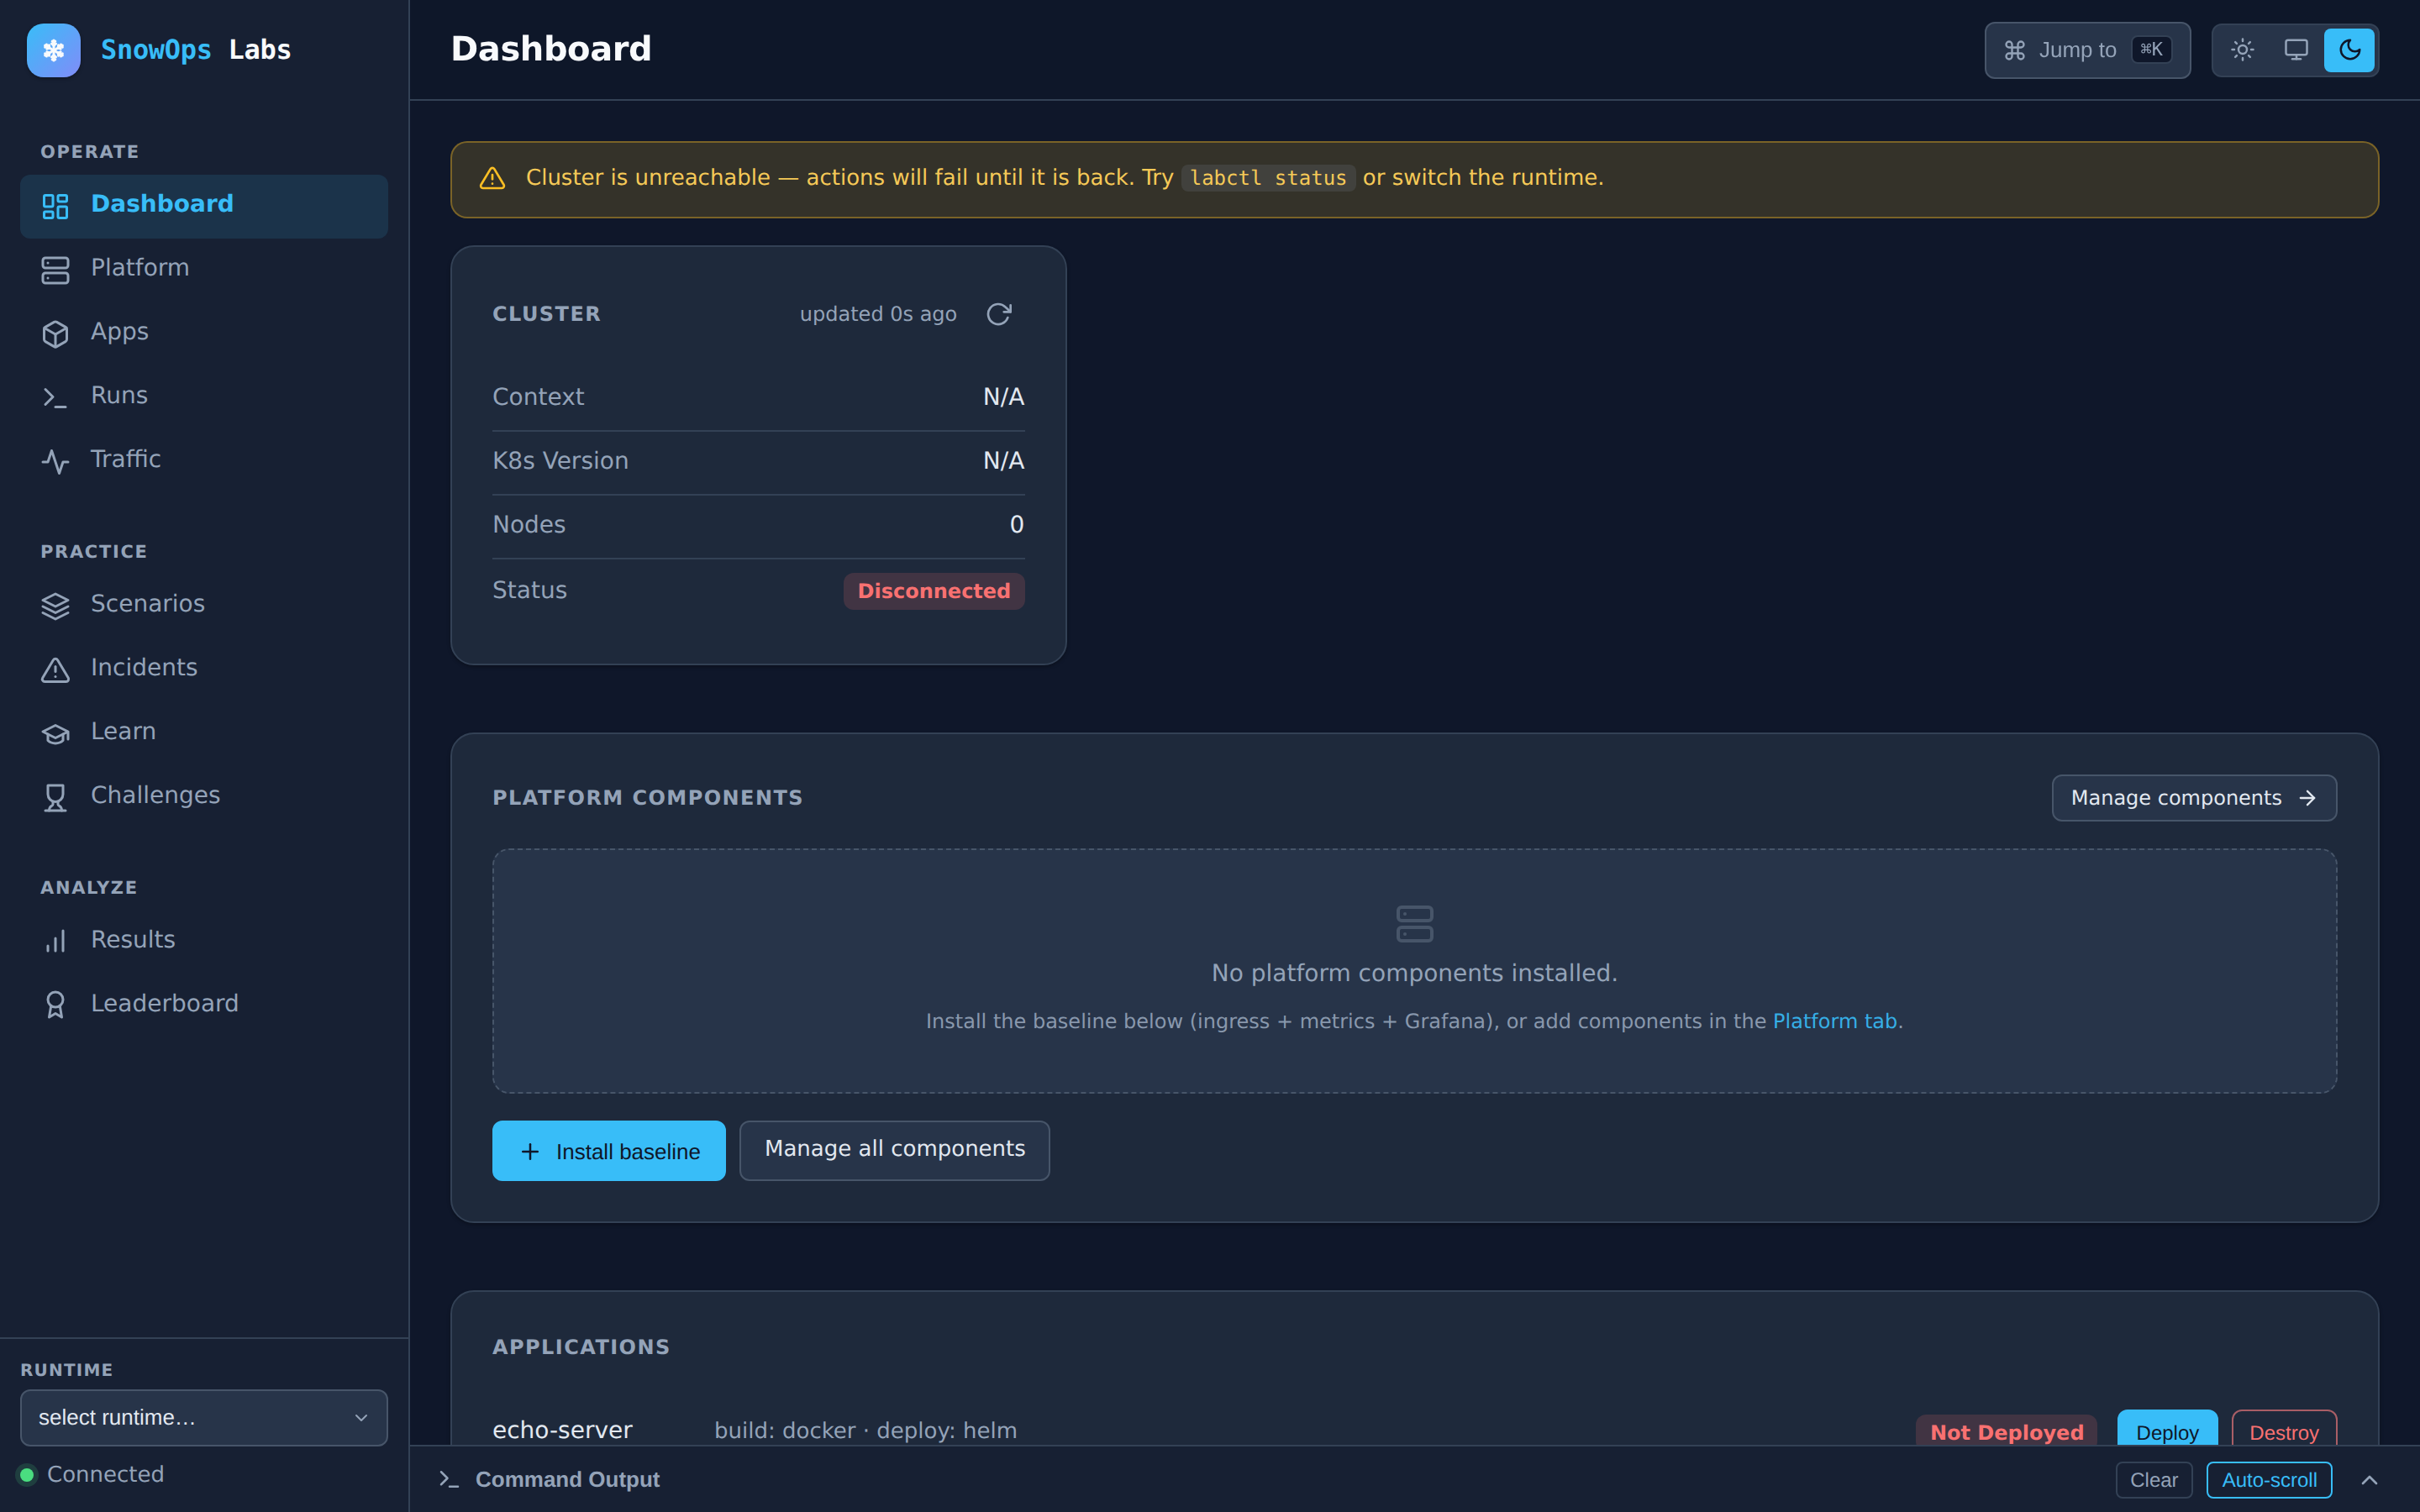
  • The dashboard showing cluster status, platform components and app controls.
    Operate hub
Who it is for

The parts of the job you can't rehearse at work

Production is usually the only place these skills get tested, and it is the worst place to learn them.

  • Engineers levelling up

    Learn → scenario → incident

    Work through a path and come out able to debug that kind of failure on your own.

  • Platform teams choosing tools

    Build → swap provider → compare

    Run the same scenario on Istio and on Linkerd, and decide with evidence in a day instead of a month.

  • SREs running game days

    Break → measure

    Surprise faults, a shared cluster and recorded time to resolve, without weeks of setup.

  • Leads assessing skills

    Challenge → leaderboard

    Timed challenges graded by the cluster give a fair, repeatable read on incident response.

Open source first

Free on your laptop, hosted later

The open-source lab is the product today, and it stays free. A hosted version is something we want to build in the long run, once enough people use the lab.

  • Available now

    Local lab

    Everything on this site runs on your own machine today. Free, open source, and yours to read and change.

    • Docker with 2 CPU / 4 GB
    • macOS, Linux or Windows with WSL2
    • Every scenario, fault and challenge
  • Long-term goal

    Hosted labs

    The same scenarios on a cluster we run, opened in a browser. We'll build it once the open-source lab has a solid base of users, and what it looks like will depend on what they need.

    • For when running Docker locally isn't an option
    • Built on the open-source lab, never instead of it
    • Shaped by what open-source users ask for
Open source, Apache-2.0

If you can write YAML, you can contribute

The Go code runs, records and grades. The lab content itself is YAML and shell, so adding a scenario or a fault never means touching the engine.

  • Write a scenario

    Scenarios, faults, paths and checks are YAML plus shell scripts. If you can write YAML, you can add to the lab. No Go required.

    Your first scenario
  • Pick up an issue

    Good first issues are labelled, and the PR bar is written down, so you know what review will ask for before you start.

    Good first issues
  • Improve the docs

    The docs live next to the code and this site publishes them. Fix a line in the repo and it shows up here on the next sync.

    Contributing guide
  • Tell us what broke

    It's an early release and it moves fast. A bug report with your labctl doctor output and the command that failed helps a lot.

    Open an issue

Your next incident should not be your first one.

Free and open source. Clone it, run the installer, and the first lab is up in about ten minutes.

shell
git clone --branch stable https://github.com/sagar2395/snowopslabs.git
cd snowopslabs && ./install.sh
labctl init

You need Docker with at least 2 CPUs and 4 GB of memory and about 10 GB of free disk. On macOS, labctl init sets up colima at that size for you. Heavier scenarios such as Kafka or a service mesh want 6 GB.

Get updates

New scenarios and faults, release notes, and news about hosted labs if and when there is some. A few emails a month at most.

We'll email you about new releases, new lab content and paid offerings such as hosted labs, courses and workshops. Unsubscribe any time.